Leaderboards disagree because they are measuring different things, on different test sets, with different scoring rules, under different conditions. One board runs a fixed multiple-choice exam. Another collects millions of blind human votes. A third aggregates a composite of ten evaluations. When one model tops Chatbot Arena and another tops the Artificial Analysis Intelligence Index, neither board is wrong. They are answering different questions. The practical takeaway: use leaderboards to shortlist, not to decide.
Leaderboards are not measuring the same thing
There are two families of public AI leaderboards, and they answer fundamentally different questions.
Static benchmark boards run every model against a fixed set of test questions and report accuracy. MMLU, GPQA Diamond, and Humanity's Last Exam work this way. These boards measure performance on a frozen exam — how many questions the model answered correctly under standardized conditions.
Human-preference boards show two anonymous answers to real users, collect pairwise votes, and convert them into an Elo-style ranking. LMArena (formerly Chatbot Arena) is the most-cited example, with over 2 million human votes. These boards measure which answer a reader prefers in a blind taste test.
A model can top the human-preference board by producing answers that feel helpful and well-formatted, while scoring mid-tier on a static benchmark that rewards factual recall or precise reasoning. A model can top a reasoning benchmark while producing answers that users find terse or unpleasant to read.
The Artificial Analysis Intelligence Index takes a third approach: it aggregates ten independently run evaluations into a single composite score covering reasoning, coding, math, and other capabilities. This is useful for comparing models across dimensions, but it makes its own set of assumptions about how those ten evaluations should be weighted relative to each other.
The result is a landscape where the same model can rank first on one board, third on another, and fifth on a third — and all three rankings can be perfectly accurate.
Same capability, different questions: the measurement noise problem
Even when two boards claim to measure the same capability, they rarely produce the same ranking.
A 2026 study applying Confirmatory Factor Analysis to over 4,000 models from the Open LLM Leaderboard found that current reporting practices underestimate the strength of relationships between benchmarks. More importantly, it found evidence of local dependence among leaderboard items — meaning that questions within a benchmark are not independent measurements of a single underlying capability. The same total score can combine general capability, benchmark-specific quirks, item redundancy, and evaluation artifacts in unknown proportions.
Another paper analyzed 11 popular LLM benchmarks comprising 41,871 individual test items and found "significant and varied shortcomings in their measurement quality". Even benchmarks designed to measure similar underlying capabilities produced inconsistent leaderboards, leading to "substantial ranking variations for the same model".
This is the core problem. A benchmark score is not a direct measurement of "reasoning" or "knowledge". It is a summary of how a model performed on a specific set of questions, presented in a specific format, scored by a specific rule. Change any one of those variables, and the score changes. The label on the benchmark stays the same, but the measurement does not.
Data contamination: when the model has already seen the test
Language models are trained on internet-scale datasets. Benchmarks are published on the internet. The overlap is not hypothetical.
When a model has seen benchmark questions during training, it is not reasoning through the problem. It is recalling the answer from memory. The benchmark score reflects memorization, not capability.
The evidence is measurable. When researchers asked GPT-4 to refill a masked MMLU answer option, the model recovered the exact option 57% of the time. ChatGPT recovered it 52% of the time. These are not reasoning scores. They are recall scores.
A systematic review of 55 studies on benchmark contamination found that all three top-ranked 7B models on the Open LLM Leaderboard were significantly contaminated.
Contamination does not always reorder leaderboards — the models at the top tend to be the ones with the most training data, and they would likely be at the top regardless. But it inflates absolute scores, compresses the gaps between models, and makes it impossible to tell whether a 2-point lead reflects genuine capability or better memorization.
Benchmark saturation: when everyone scores 98%
Several of the most widely cited benchmarks have stopped being useful for comparing frontier models.
MMLU, the Massive Multitask Language Understanding benchmark, tests models across 57 academic subjects with multiple-choice questions. In 2026, frontier models score 97–99% on MMLU. The top five models are separated by just 2 points.
GSM8K (grade-school math) and HumanEval (coding) are similarly saturated. Frontier models score 95% or higher on all three.
The problem is not that models have become perfect. It is that the tests have run out of headroom. A benchmark where every serious contender scores between 97% and 99% cannot distinguish between them. The remaining 1–2% gap is within the range of measurement noise, random variation, and prompt-format sensitivity.
MMLU-Pro was designed to fix this by using 10 answer choices instead of 4, reducing the role of random guessing, and adding questions that require multi-step reasoning rather than recall. On MMLU, the top models are within 2 points. On MMLU-Pro, the spread widens to 11 points.
This is the difference between "all models are basically the same" and "there are real performance differences here" — and it depends entirely on which benchmark you read.
Prompt format sensitivity: the same model, different scores
A model's benchmark score is not just a function of the model. It is a function of how the questions are presented.
A study published at ICLR 2024 found that prompt format alone swung LLaMA-2-13B's accuracy by up to 76 percentage points on meaning-identical prompts. The questions were the same. The model was the same. The only variable was how the prompt was phrased.
This is not a quirk of one model or one benchmark. Zero-shot, few-shot, chain-of-thought, and self-consistency sampling all produce different scores from the same model on the same questions.
Leaderboards try to standardize the prompt format across models. But models are trained on different data with different formatting conventions. A prompt structure that flatters one model may handicap another. The leaderboard's "standardized" format is itself a choice — and that choice influences the ranking.
Style bias: why human-preference boards reward more than accuracy
Human-preference boards like LMArena have their own set of distortions.
One is length bias: longer answers tend to receive more votes, regardless of whether the extra length adds useful information. LMArena measured a 0.249 length coefficient, meaning that answer length has a statistically significant effect on preference votes.
Another is formatting bias: answers with headers, bullet points, bold text, and tables tend to be preferred over plain prose, even when the content is equivalent.
When LMArena introduced style controls to correct for these biases, the ranking shifted dramatically. Grok-2-mini moved from 6th place to 18th once style effects were accounted for.
This does not mean human-preference boards are worthless. They measure something real: which answers people actually prefer when using AI in everyday conversation. But "preferred by a casual user in a blind test" is not the same as "best for a specific professional task". A model that wins votes by writing long, well-formatted answers may be worse at strict JSON extraction or precise code generation than a model that writes terser responses.
Scaffold inflation: the score is not the model
This is the most underappreciated source of leaderboard disagreement, particularly for agentic benchmarks.
When a model provider publishes a SWE-Bench score — a benchmark that measures whether an AI agent can complete real software engineering tasks — that number does not represent the base model's performance. It represents the base model wrapped in proprietary scaffolding: Python scripts, linters, retrieval systems, retry logic, and multi-agent orchestration tuned for the benchmark.
The scaffolding does a significant portion of the work. Deploy the same base model in your own scaffold — which is what you will actually do in production — and performance drops. Sometimes dramatically.
This means two leaderboards can report different scores for "the same model" because they are not measuring the same thing. One is measuring the model plus a vendor's optimized toolchain. The other is measuring the model plus a different toolchain, or the model alone.
Commercial incentives: who is paying for the evaluation?
A 2026 paper examining the limitations of general LLM rankings identified commercial incentives as a structural problem. External evaluations are often funded by the companies whose models are being evaluated. This creates dependencies that can influence which benchmarks are selected, how results are reported, and which comparisons are emphasized.
The paper also notes differences between evaluated and publicly available systems. A model configuration that scores well on a leaderboard may not be the same configuration that is available to the public through an API or consumer app. The leaderboard measures one version; you get another.
This is not an accusation of fraud. It is a structural feature of an industry where the entities being measured are also the entities funding the measurement. A benchmark that produces unfavorable results for its funder is less likely to be repeated.
What leaderboards are actually good for
None of this means leaderboards are useless. It means they are being used for the wrong purpose.
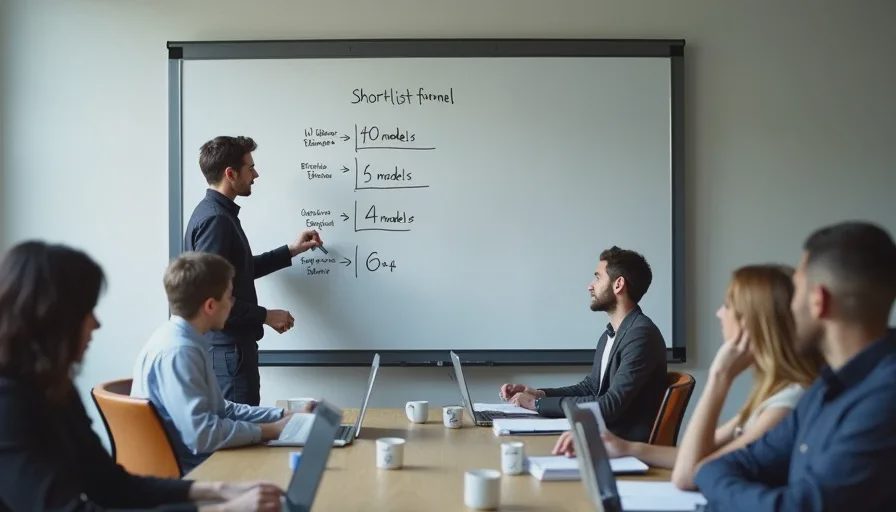
Leaderboards are good for shortlisting. If you have 40 models to choose from, a leaderboard can narrow the field to 4. That is a real and valuable function. The cost of running your own evaluation on 40 models is prohibitive; the cost of running it on 4 is manageable.
Leaderboards are bad for deciding. A high rank does not establish that a model follows your instructions, handles your inputs accurately, or produces an improvement worth its cost. A leaderboard answers a question about a general population. You are asking about a single distribution: your prompts, your formats, your edge cases.
The researchers who documented the measurement noise in leaderboard ecosystems put it plainly: general rankings can inform model selection but "do not replace evidence about performance on the intended work".
How to read a leaderboard without being misled
1. Check what the benchmark actually measures. A multiple-choice exam measures recall and pattern-matching. An open-ended benchmark measures generation. A human-preference board measures likeability. A composite index measures whatever its creators decided to weight. None of these is "general intelligence."
2. Check for saturation. If the top 5 models are separated by 2 points, the benchmark has run out of signal. Look for a harder version of the same benchmark — MMLU-Pro instead of MMLU, LiveCodeBench instead of HumanEval — before drawing conclusions.
3. Check the date. A benchmark published more than a year ago has almost certainly leaked into training data. Cross-reference with contamination-resistant alternatives that use problems released after model training cutoffs.
4. Check what configuration was tested. If the leaderboard used a vendor's scaffolding, the score reflects the system, not the model. Your production scaffold will produce different numbers.
5. Check whether style controls are applied. On human-preference boards, uncontrolled rankings reward length and formatting. If the board does not correct for these, treat the ranking as a popularity contest, not a capability measurement.
6. Run your own evaluation on your own data. Build a golden set of 50 real prompts from your actual workflow. Run your shortlisted models against them. Score on task pass rate, not public rank. This is the only measurement that predicts your results.
FAQ
Why do leaderboards disagree about which model is best?
Because they are measuring different things. Static benchmarks measure accuracy on a fixed test set. Human-preference boards measure which answers people prefer in blind comparisons. Composite indices aggregate multiple evaluations with different weightings. A model can win one category and lose another without any contradiction.
Which leaderboard should I trust?
None of them, entirely. Use leaderboards to shortlist — to narrow 40 models down to 4. Then run your own evaluation on your own tasks. Public benchmarks tell you what to shortlist. Only evaluation on your own data tells you what to ship.
What is benchmark contamination?
Benchmark contamination happens when test questions leak into a model's training data. The model has seen the questions before and is recalling the answers rather than reasoning through them. This inflates scores without any corresponding improvement in real capability. A systematic review found that all three top-ranked 7B models on the Open LLM Leaderboard were significantly contaminated.
Why do so many models score 98% on MMLU?
Because MMLU has saturated. The benchmark was designed in 2020, when models struggled to beat 50%. Frontier models now score 97–99%, leaving almost no room to differentiate between them. MMLU-Pro addresses this with harder questions and 10 answer choices instead of 4, creating a wider spread.
Does a higher LMArena Elo score mean the model is better?
It means human voters preferred its answers in blind comparisons. That is a meaningful signal, but it is influenced by style factors like answer length and formatting. When LMArena applied style controls, Grok-2-mini dropped from 6th to 18th place. Elo measures likeability as much as capability.
What is scaffold inflation?
Scaffold inflation happens when a benchmark score reflects not just the model but also the proprietary tooling wrapped around it — scripts, linters, retrieval systems, retry logic. The scaffolding does a significant portion of the work. Your production environment will not have the same tooling, so your results will differ.
How should I choose a model if I cannot trust the leaderboards?
Start with a leaderboard to shortlist three or four models. Then build a set of 20–50 real prompts from your actual workflow. Run each model against your prompts. Score on whether the output is usable, not whether it sounds impressive. Re-run the test when a new model is released or a price changes. The model that wins on your tasks is the model you should use.
Letters
No letters yet — be the first to write.